Voice AI Benchmark: Retell Ranks #1 for Medicare Workflow Accuracy
5
MIN READ
August 19, 2026
A new voice AI benchmark took one Medicare insurance agent, put it on six different platforms without changing a line, and measured which one actually followed the workflow. Retell finished first.
The test is Cekura's. Cekura builds automated QA and testing tools for voice agents and publishes voice AI benchmarks. Its Medicare workflow study (Study 02, July 2026) ran 414 calls in total and scored each platform on how reliably it handled a regulated insurance conversation.
Disclosure: Retell AI publishes this summary and is one of the six platforms Cekura tested. Retell did not run or grade the test. Cekura is also a Retell app partner.
Retell led the field at 95.7% workflow accuracy, clearing 22 of the 23 evaluators. Across all six platforms, workflow scores ranged from 65.2% to 95.7%, even though every platform ran the same agent.
TL;DR
Cekura deployed one byte-identical Medicare agent across six voice platforms and ran 414 calls.
Retell ranked #1 at 95.7% workflow accuracy, passing 22 of 23 evaluators.
Workflow scores across the field ran from 65.2% to 95.7%, even though every platform ran the same agent.
Retell also held first place under strict end-to-end grading, which counts runtime failures, again at 95.7%.
The 23 evaluators cover consent, required disclosures, routing, privacy and consumer-protection limits, the moments where a regulated Medicare call goes wrong.
Cekura deployed the same Medicare TPMO agent on each of the six platforms and describes it as byte-identical, so the platform running underneath was the thing being compared.
A TPMO is a third-party marketing organization, the kind of licensed agency that sells Medicare Advantage and Part D plans. These calls are tightly regulated, so the agent has to get a lot right, and in a fixed order.
The benchmark used 23 evaluators, each targeting a point where insurance calls tend to break. They fell into four groups: opening the call and getting permission, working out what the caller actually needs, qualifying and capturing the lead, and staying inside consumer-protection limits.
Every evaluator ran three times on each platform, and a platform earned credit only if all three runs passed, a measure Cekura calls pass3. Twenty-three evaluators, three runs each, across six platforms works out to the full 414 calls. You can read the methodology, all 23 evaluators and the per-platform runs on Cekura's study page; the call count is on its experiments index.
Here is how the six platforms scored, ordered by workflow accuracy:
| Platform | Workflow pass3 | Strict end-to-end pass3 |
|---|---|---|
| Retell | 95.7% (22/23) | 95.7% (22/23) |
| ElevenLabs | 91.3% (21/23) | 91.3% (21/23) |
| Pipecat | 82.6% (19/23) | 73.9% (17/23) |
| LiveKit | 73.9% (17/23) | 73.9% (17/23) |
| Synthflow | 69.6% (16/23) | 8.7% (2/23) |
| Vapi | 65.2% (15/23) | 65.2% (15/23) |
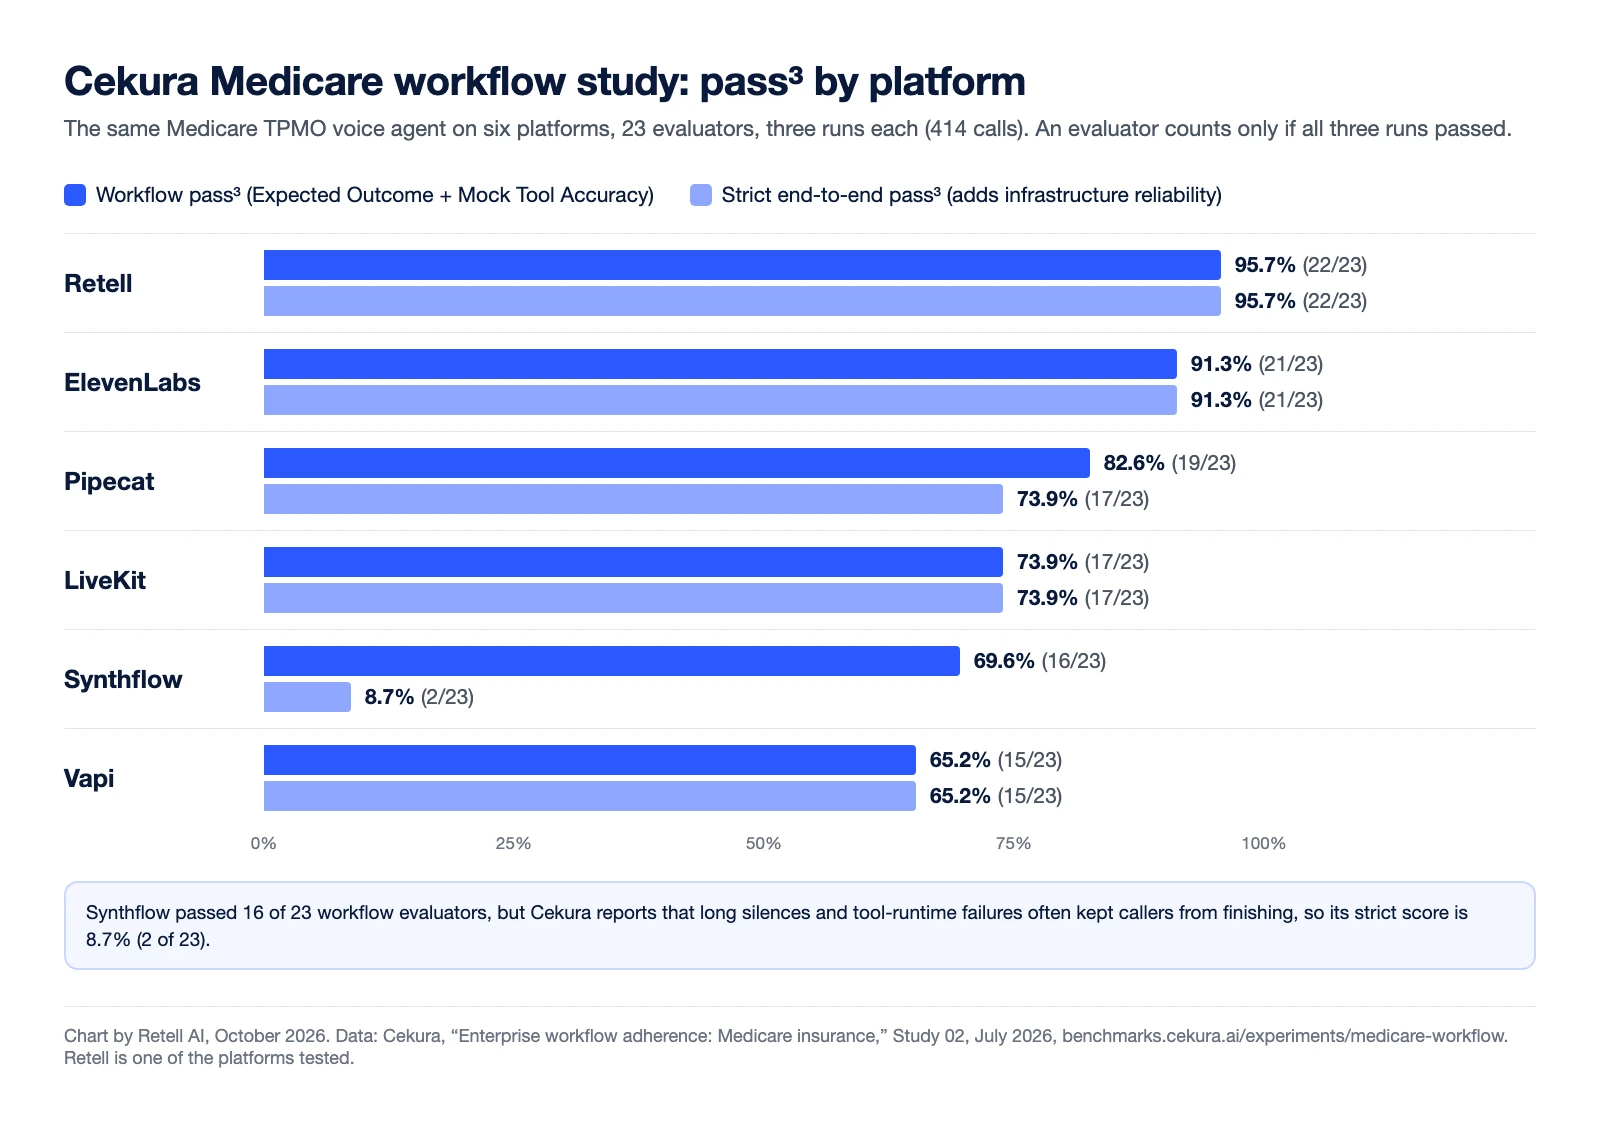
Retell was the only platform to clear 95% on workflow accuracy, and it kept that score under the stricter measure explained below.
Cekura reported two scores because a voice agent can fail in two different ways.
Workflow pass3 asks whether the agent chose the right action and called its tools correctly. It uses two signals Cekura calls Expected Outcome and Mock Tool Accuracy.
Strict end-to-end pass3 adds a second question: did the caller actually get through the task? It also counts infrastructure failures that prevent a caller from completing the task, even when the intended action was right.
Retell scored 95.7% on both, so it did not lose ground to runtime problems. Some platforms did. Synthflow passed 16 of 23 evaluators on workflow accuracy but only 2 of 23 under strict grading. Cekura reports that long silences and tool-runtime failures often prevented callers from finishing.
On a Medicare sales call, the agent is not just answering questions. It has to deliver the required disclosure, earn consent before discussing plans, avoid giving personalized advice, and route the caller to a licensed human at the right time.
Those steps are set by federal TPMO rules, and skipping one is a compliance problem, not a rough edge.
That is what the 23 evaluators probed. A caller interrupts the disclosure and demands plan details. A family member calls on behalf of a beneficiary. A caller asks the agent to promise that a plan covers their medication. The right move in each case is specific, and a platform that stalls or improvises fails the caller and the compliance record at once.
The benchmark shows that running the same agent is not enough. The platform underneath decides whether that agent holds up on the highest-risk calls.
It is a separate, focused study. Cekura says the Medicare experiment is reported separately from its current Benchmark v1 leaderboard, which runs a different test set: nine platforms, 82 scenarios, three runs each.
On that main leaderboard (last updated October 22, 2026), Retell ranks second on pass3 reliability at 75.6%, behind PolyAI at 87.8%. Read the Medicare result as evidence about one regulated, multi-step workflow, not as a ranking across every kind of call.
Copy the method, not the score. Cekura's numbers describe its agent and its evaluators. Your agent, prompts and integrations will behave differently, so test the calls that matter to you.
Write evaluators from your hardest moments. List the points where your calls break: a required disclosure, consent, a caller who changes their mind, a request the agent must refuse. Each one becomes a test case with a clear good outcome.
Grade the action, not just the words. Cekura's workflow score checks tool use as well as the outcome. In Retell simulation testing, an AI plays the caller, success criteria grade each run pass or fail, and custom function mocks stand in for your real tools.
Run every case more than once. A Retell batch runs each selected case once, so duplicate the case or rerun it, and only count a scenario as passing when every run passes. That is the idea behind pass3.
Keep scoring after launch. AI QA scores a sample of real calls on metrics such as tool call accuracy, hallucination and resolution rate, with transcript evidence for each failure.
Retell is a platform for building, testing, deploying, and monitoring AI voice agents that make and take phone calls. The benchmark rewarded two things Retell is built around: following a multi-step workflow and calling tools correctly under pressure.
Warm transfer to a licensed human: when a caller needs a person, the agent hands off with the context it already gathered, using call transfer.
Answers from a knowledge base, not off-script advice: the agent pulls factual answers from a connected knowledge base and stays inside what it is allowed to say.
Every call reviewed after the fact: teams use post-call analysis and AI quality assurance to see where a flow held up and where it slipped.
Built for regulated industries: Retell runs voice agents for teams in healthcare and insurance, where the order of operations on a call is not optional.
This is one Cekura study on one workflow, and results vary by how an agent is built and maintained. On that hard, regulated task, Retell came out ahead of the five other platforms tested.
A voice AI benchmark is a controlled test that runs the same task across different voice-agent platforms and scores how well each one handles it. Cekura's version uses repeated calls and fixed evaluators so the comparison stays fair.
Cekura, a company that builds testing and QA tools for voice agents. Retell did not run the test or grade itself. Retell is one of the six platforms tested, and Cekura is a Retell app partner.
A platform had to pass an evaluator on three separate runs to get credit for it. One lucky run does not count, which makes the score a test of consistency rather than a single good call.
Yes. Cekura deployed the same byte-identical Medicare agent on all six platforms. In its words: same agent, same workflow, very different reliability.
Cekura publishes the per-platform runs, the scoring method and a breakdown of all 23 evaluators on its Medicare workflow study page.
No. Retell led this Medicare workflow study. On Cekura's separate main leaderboard, last updated October 22, 2026, Retell ranks second on pass3 reliability at 75.6%, behind PolyAI at 87.8%.
Build a voice agent that holds up on the hard calls.
Retell lets you build, test, and launch an AI voice agent, then watch how it performs on every call. Try Retell free or talk to sales.
See how much your business could save by switching to AI-powered voice agents.
Total Human Agent Cost
AI Agent Cost
Estimated Savings
A Demo Phone Number From Retell Clinic Office